This action will delete this post on this instance and on all federated instances, and it cannot be undone. Are you certain you want to delete this post?

Rahul Gopinath posted Oct 21, 2024
There was site that once showed the change in participation in platforms such as Mastodon and Bluesky in response to Twitter/X's change in management. Does anyone know where to find this? One of my students is investigating ActivityPub, and it would be nice to be able to show the change in participation in Fediverse over time.
Rahul Gopinath posted Oct 2, 2024
Notebook LLM is awesome, but very much a work in progress. For example, while I can provide multiple sources, there is no way to preview PDFs or even download them once I have added one of these as source material. Secondly, the source guide extraction of text leaves a lot to be desired. While the RAG is very useful, when I click on the citations, I wish it took me to the actual document rather than an extracted summary of it. I also wish that there was a way to query individual documents separately.
Rahul Gopinath posted Sep 24, 2024
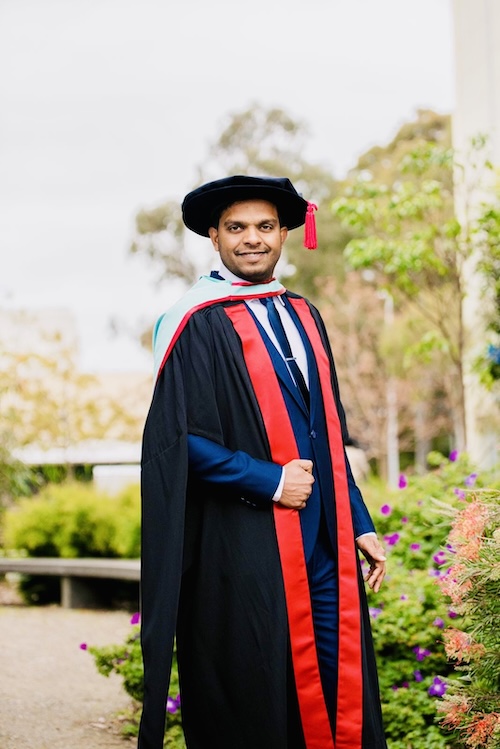
Danushka Liyanage, postdoctoral researcher at University of Sydney Software Engineering group at his convocation.
Congratulations Dr. Liyanage!
Rahul Gopinath posted Jul 10, 2024
Google has just published their scholar ranking for publication venues here (The link is for software systems).
Rahul Gopinath posted Jul 9, 2024
I am somewhat new to the world of complex spreadsheets (Never had to use them before except as pretty CSV viewers). I am surprised that Excel does not allow us to rename columns to intuitive names so that I can say `=Total/Max` rather than `=S2/T2`. Is there any spreadsheet that allows this?
Rahul Gopinath posted Jul 2, 2024
I have posted about a related issue before, but it seems that it is time to take a harder look at using CVEs as the touchstone for effectiveness of security tools. It has become far too easy to produce CVEs (even high severity ones) because there is limited oversight in the whole process. If you are a security researcher wondering how to evaluate your tool, please consider using Mutation Analysis as the metric. It is a well researched technique that can reliably show how your tool performs, and provide you insights with where you can improve.
Rahul Gopinath posted Jun 23, 2024
Just recently read the paper "Delving into ChatGPT usage in academic writing
through excess vocabulary". by Kobak et al. Their premise is that (from the abstract) the [models] can produce inaccurate information, reinforce existing biases, and can easily be misused. So, the authors analyse pubmed abstracts for vocabulary changes, and identify certain words that have become more common post LLM. They find that words such as "delves", "showcasing", "underscores", "intricate", "excel", "pivotal", "encompassing", "enhancing" are all showing an increased usage, and hence suspect.
While this data is indeed interesting, I wonder why LLMs tend to use these words. Aren't LLM outputs supposed to be more of a reflection of the data they are fed in training? Surely that means that these words are more common in some data set than we expect?
Rahul Gopinath posted Jun 22, 2024
Our paper "Empirical Evaluation of Frequency Based Statistical Models for Estimating Killable Mutants" on evaluation on models for estimating equivalent and killable mutants were accepted by ESEM 2024. The paper is here. #ESEM2024 #Equivalentmutants #mutationanalysis
Rahul Gopinath posted Jun 10, 2024
I am visiting ANU Canberra on Friday. If you are around, and is interested in what I do, please come talk to me.
Rahul Gopinath posted Jun 2, 2024
Parsing JSON is indeed a minefield. However, a commenter in HN has a suggestion: Use postscript instead of JSON. It has a binary format, has comments, and generally looks much better. Here is their provided example:
  <<
    /first_name (John)
    /last_name (Smith)
    /is_alive true
    /age 27
    /phone_numbers [
      <<
        /type (home)
        /number (212 555-1234)
      >>
      <<
        /type (office)
        /number (646 555-4567)
      >>
    ]
    /spouse null
  >>
And I agree, it is much better than JSON. There are many other interesting things to like here. For one, the keys are symbolic. There is only one character `/` indicating the keys in a dictionary (indicated by `<<`). This reduces the visual clutter to a great extent. Using `<<` for dictionaries is also great. Dictionaries are one of the largest units in such formats containing data, and it is better to use two characters for their delimiters. By using `()` for strings, it provides a starting and ending delimiter for strings, and is better visually parsable than `"`. There are no commas in arrays. or dictionaries, removing the question of trailing commas. Overall, PON (Postscript Object Notation) is much better designed than JSON for human readability.